AI infrastructure / Open weights
AI Is Getting Better. Running It Yourself Is Getting Harder.
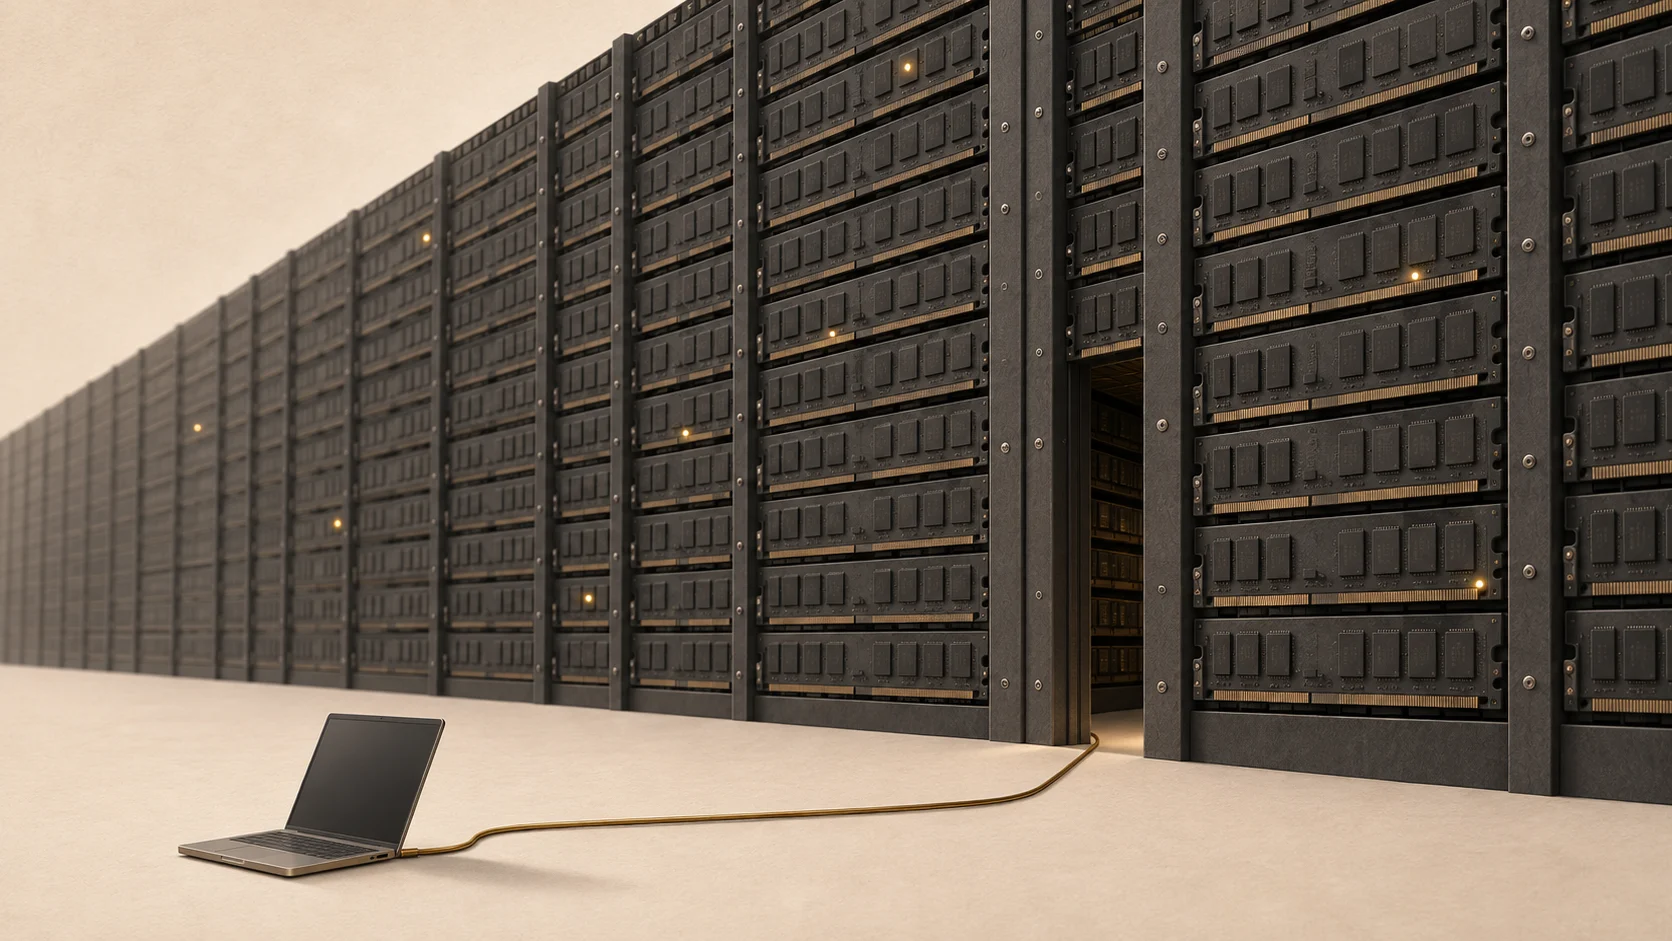
A model can become cheaper to compute and harder to own.
A lab releases a better model. The weights are public, the benchmarks look good, and developers start figuring out what they can build with it.
Then they check the memory requirements.
I think this is going to become one of the harder problems for the open-source AI community. Models can become more efficient at generating tokens while becoming harder for individuals and small teams to host. We could gain access to increasingly capable weights while losing the practical ability to run them ourselves.
A model does not need a restrictive license to become inaccessible. The hardware bill can do that.
The part you don’t activate still needs somewhere to live
Chinese and US labs have both pursued large Mixture-of-Experts models. DeepSeek-V3 has 671 billion total parameters, with 37 billion activated per token. Meta’s Llama 4 Maverick has 400 billion total parameters, with 17 billion active. These are examples of the direction, rather than proof that every future model will follow it. DeepSeek’s technical report, Meta’s model card
The appeal is straightforward. A model contains many expert networks, and a router selects a subset for each token. It can have a large pool of parameters without using all of them on every generation step.
That makes the distinction between total and active parameters economically important.
Active parameters help determine the work required for a token. Total parameters determine how many weights you need to keep somewhere. The rest of the serving system adds its own requirements, including working memory, context caches, and communication between devices.
You can skip an expert’s computation. You still need access to its weights when the router selects it.
At one byte per parameter, a hypothetical trillion-parameter model would require roughly a terabyte for the weights alone. Compression can reduce that footprint, but the underlying problem remains: a model can be relatively economical to compute and expensive to keep ready.
For a large provider, that may be a good trade. For somebody trying to run it independently, it may be the deciding constraint.
Efficiency can favor the largest operator
Imagine a provider hosting that model for thousands of customers.
The weights are loaded once per serving replica. Requests share the deployment, and batching lets the server process work from multiple users together. Inference engines such as vLLM are built to improve this kind of utilization. vLLM’s serving research
An individual running a few coding agents has a different problem. The model may sit mostly idle between requests, but its memory footprint does not shrink while it waits.
Ten agents can share one model deployment. They do not require ten copies of the weights. They do, however, add context storage and competing work. Sharing helps; it does not make the original hosting requirement disappear.
This is how architectural efficiency can reinforce economies of scale. A provider can spread expensive memory and interconnects across a busy service. A small team has to justify the same infrastructure against a much smaller workload.
The weights can be equally available to both. The economics are not.
Public weights still matter
I would still rather have the weights.
They allow independent hosting, modification, research, and competition among providers. They give organizations options that an API alone cannot provide. Even if I cannot run a model at home, somebody outside the original lab can operate it.
But there is a meaningful difference between choosing a provider and being able to replace one with your own deployment.
If the most capable releases require infrastructure beyond the reach of ordinary developers, much of the community will experience them through hosted endpoints. We may have more competing services while remaining dependent on services.
That is the risk I see: open-weight AI becoming centralized in practice as the cost of useful self-hosting rises.
Nobody has to withdraw the download.
The community needs a smaller bill
Shared infrastructure helps pay for the requirements. Research can reduce them.
Compression, distillation, better inference software, and expert caching all matter because they can change who gets to operate a model. Offloading research already investigates ways to run sparse models without keeping all weights in GPU memory, though moving experts between memory tiers introduces its own performance costs. MoE offloading research
The useful question is how much capability survives under a realistic budget.
Can a smaller model perform the work a team actually needs? Can frequently used experts stay in fast memory while the others remain elsewhere? Can better batching support more users without making each interaction painfully slow?
Those improvements rarely produce a headline as simple as “another trillion parameters.” They can have a more direct effect on accessibility.
A model that a small organization can afford to operate gives that organization choices. A model it can only download gives it a file.
I expect large labs to keep pursuing scale wherever scale produces better results. The open-source community’s opportunity is to make those results cheaper to reproduce, adapt, and serve.
The release I most want to see is a capable model whose hardware requirements let more people say: we can run this ourselves.
Comments
Join the conversation. Just a nickname—no account or email needed. Comments are public; nicknames are not verified. Reply to any comment to keep the conversation going. Your nickname is remembered on this browser. Please keep it thoughtful and on topic.