Draft / AI architecture & hardware
Before AI Can Rewrite Itself, We Need to Rethink the Machine
What modular models could change about learning, computing, and understanding AI.
The Fantasy of a Brain That Rewrites Itself
People love the sci-fi image of an AI sitting in a server rack, casually rewriting its own source code and upgrading its own brain in real time. It is a thrilling story: a system that discovers a flaw in its thinking, edits its internal connections on the fly, and emerges smarter a millisecond later.
The practical difficulty is that modern artificial intelligence does not work like a clean library of code. In today's models, knowledge overlaps everywhere. A single concept is not stored in a single digital folder; it is tangled across billions of numbers simultaneously. When you try to adjust a few numbers to teach the model a new skill or patch a mistake, you inevitably disturb other abilities it already possessed. In computer science, this is known as catastrophic forgetting. The model might learn the new trick, but it forgets how to balance a simple equation or write clean grammar.
If we ever want a system that updates its own mind safely, we cannot just tell current models to edit themselves. We have to build an architecture designed to accommodate change from the very start.
The Old Way: The Mega-Brain / The New Way: Micro-Experts
For the last several years, the dominant trend has been the monolithic mega-brain. When you type a prompt into a standard model, virtually every single parameter in the entire network activates. Even if you only asked the system to spell the word "cat," the entire multi-gigabyte structure wakes up, crunches numbers, and burns electricity.
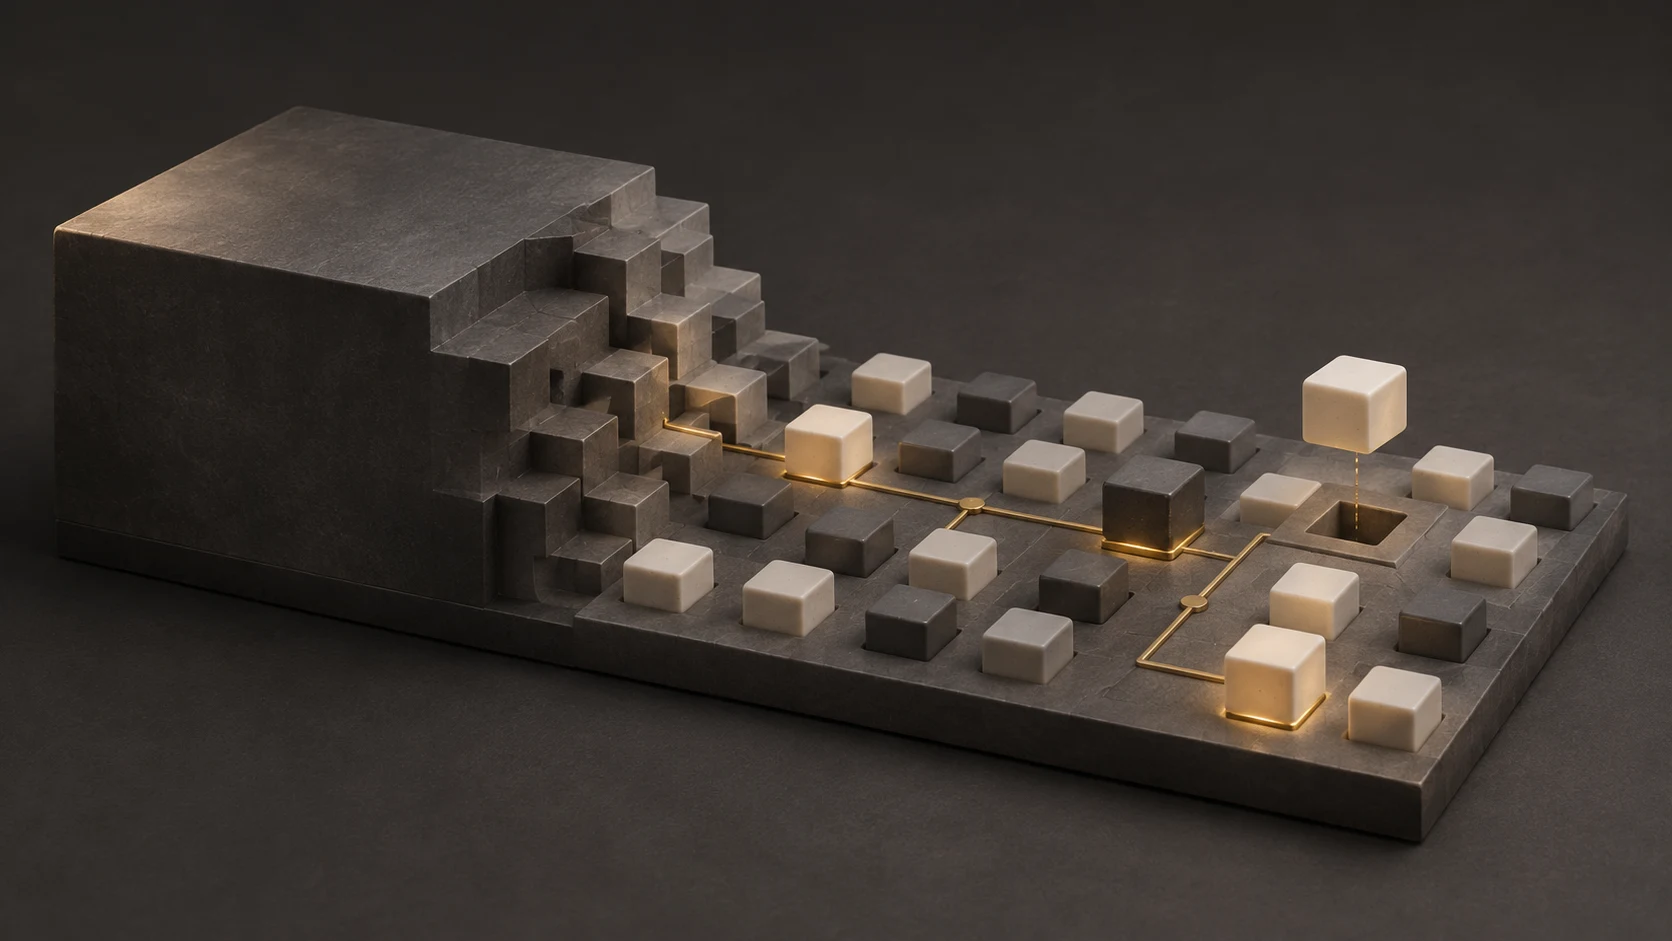
The alternative approach replaces that giant block of stone with smaller components selected for particular work.
Think of it like a pegboard on a workshop wall, or a bin of LEGO bricks. Instead of building one massive, unchangeable statue, you create thousands of distinct, small modules. When a problem arrives, the system selects only the handful of pieces required to solve it.
Versions of this selective computation already exist in production today under the banner of Mixture of Experts (MoE). But the next step pushes this concept much further: breaking large models down not into eight or sixteen hefty sub-networks, but into tens of thousands of fine-grained micro-experts.
How AI Could Write Its Own Micro-Expert
This is where the opening fantasy turns into a practical engineering mechanism: the model does not attempt dangerous open-heart surgery on its core brain, but instead writes a brand new, self-contained micro-expert directly.
In a dense network, attempting to alter weights is hazardous because you cannot predict the ripple effects. But in a fine-grained modular architecture, the system can use specialized generator layers (known in research as hypernetworks) or addressable key-value memory banks to mint a new micro-expert on the fly.
When the model encounters an unfamiliar coding dialect or a distinct corporate formatting rule, it does not need to pause for hours of slow, expensive retraining. Instead, in a single forward pass, it calculates and outputs the exact grid of numbers needed for a brand-new, isolated micro-expert.
The AI writes that new module directly into an empty slot on its pegboard. Because the core system remains completely frozen and untouched, there is zero risk of scrambling existing knowledge. The newly created module handles the fresh task, and if its output proves unhelpful or incorrect, the system simply clears that single slot. The AI adapts by manufacturing small, purpose-built tools rather than performing risky open-heart surgery on itself.
Many Experts, a Few Selected at a Time
The immediate argument for this structure is raw efficiency.
Running a massive dense model for every routine question is like hiring an entire freight train just to deliver an envelope across town. It works, but it wastes an extraordinary amount of fuel.
A modular model uses an internal routing mechanism that reads incoming tokens and calls up only the relevant specialists. A routine conversational greeting might activate a tiny fraction of one percent of the system.
Further advances push this selective processing into depth as well. Straightforward questions can exit after passing through a couple of early layers, completing their work in a fraction of a millisecond. Difficult problems, such as multi-step logic or dense legal analysis, can route through specialized reasoning loops that take more time. Simple tasks receive less computation, and hard problems receive more.
A Micro-Expert on Every Phone Starts With Simpler Math
Dividing a model into micro-experts helps organize knowledge, but running these components on everyday hardware requires making the underlying arithmetic much more affordable.
Standard neural networks rely heavily on floating-point multiplication. Every calculation involves long decimal numbers that demand complex, power-hungry circuits on a chip. This is why data centers run hot and consume so much electricity.
A promising frontier simplifies this math by constraining weights to just three values: minus one, zero, and one.
When weights are restricted to these three states, traditional multiplication vanishes from the layer:
A weight of plus one means you add the incoming value to your running total.
A weight of minus one means you subtract it.
A weight of zero means you skip the operation entirely.
The heavy, heat-generating multiplications turn into clean additions and subtractions. That shift cuts energy consumption dramatically, opening the door for capable, specialized micro-experts to run locally on phones, tablets, and laptops without draining the battery.
Could We Understand a Model Well Enough to Adjust It?
Alongside efficiency sits the equally urgent challenge of transparency and safety.
Today's models are largely black boxes. Multiple concepts share the same circuits, which makes it almost impossible to predict how a tweak will ripple through the system. Researchers are working toward a property called monosemanticity: designing or analyzing networks so that individual internal components correspond to recognizable, distinct concepts.
If an architecture achieves this clarity, diagnosing mistakes stops being an exercise in guesswork. If a model exhibits an undesirable behavior, engineers would not have to guess which billion parameters caused the error. They could locate the exact mechanism behind the mistake and adjust it directly.
The ultimate ambition is an operational safety dashboard: an interface where the dials correspond to real, identifiable behaviors. Rather than spending millions of dollars blindly retraining a model to suppress a single harmful failure mode, teams could inspect the internal circuit and dial down that exact feature directly.
Your Device, Nearby Experts, and Bigger Machines
How would this modular, low-power ecosystem feel in daily life? It avoids the extreme scenarios where everything is locked away in a central corporate cloud or forced to fit entirely on a handheld gadget.
Instead, the workload naturally balances across three tiers:
Your personal device: A lightweight, highly efficient local model handles private notes, routine drafting, and immediate tasks on your phone or laptop with zero network delay.
Nearby regional experts: When you ask a question that requires deep domain knowledge, your device routes the request to regional hubs housing libraries of micro-experts, fetching only the specific modules needed for the job.
Dedicated computing campuses: Massive data centers remain essential, but their role focuses on foundational training, heavy simulation, and scientific discovery rather than answering everyday lookup queries.
The Machine Worth Working Toward
The sci-fi dream of a machine rewriting its own mind does not have to mean an unpredictable black box altering its code in the dark.
Grounded in sound architecture, the future of artificial intelligence looks far more practical. It is a system built of modular components that can generate its own new capabilities in manageable steps without breaking old ones. It is a network that conserves energy by using simple math and activating only the parts it needs. And most importantly, it is an architecture clear enough for human engineers to inspect, understand, and guide.
Before a machine can safely improve itself, we must build a system that can handle growth without falling apart. Modular, efficient, and transparent models provide the blueprint to get there.
Comments